Zebin YaoI am a 1st-year PhD student in the Department of Computing at The Hong Kong Polytechnic University, fortunately advised by Prof. Jieming Shi. I completed my Bachelor's and Master's degrees in Computer Science at Nankai University, where I was supervised by Prof. Gang Wang and Prof. Xiaoguang Liu. |

|

|
Dynamic Detect and Fix Hardness for Efficient Approximate Nearest Neighbor SearchZhiyuan Hua, Qiji Mo, Zebin Yao, et al. Proceedings of the ACM SIGMOD International Conference on Management of Data, 2026 arxiv / website / code / We propose a novel method for improving approximate nearest neighbor search performance in out-of-distribution scenarios by introducing Escape Hardness to dynamically identify and fix defective graph regions. |
|
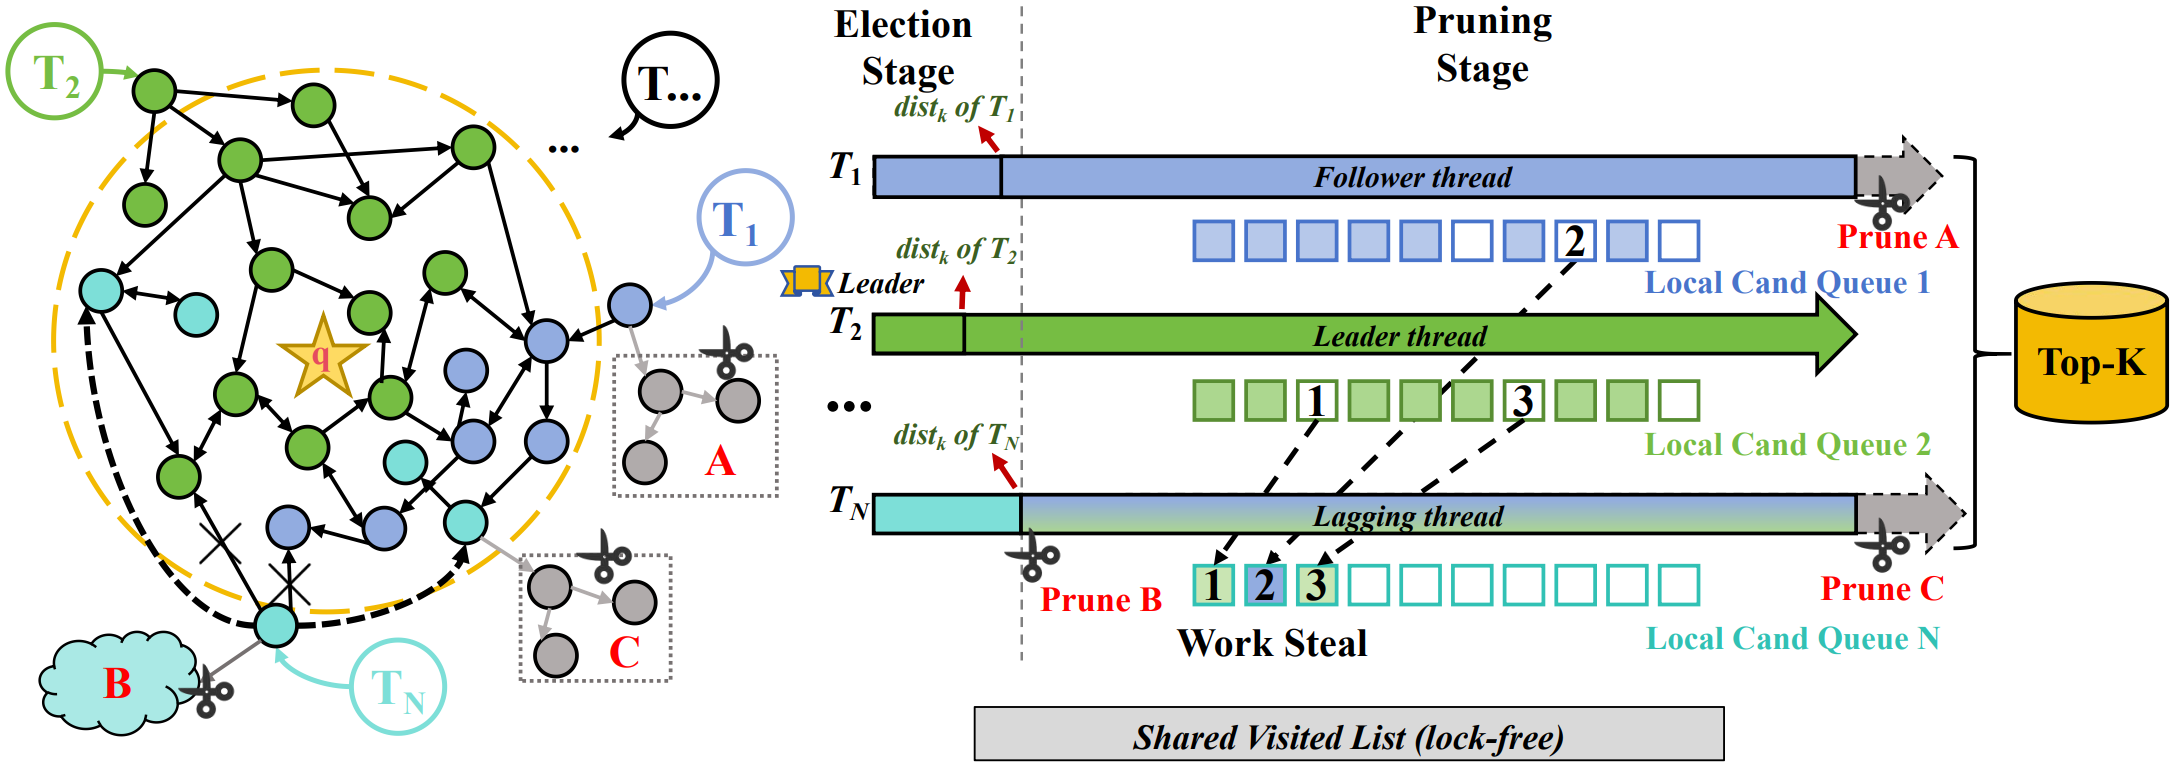
Overcoming the Sync-Compute Dilemma in Parallel Graph-Based Vector RetrievalQiji Mo, Zhiyuan Hua, Zebin Yao, Lixiao Cui, et al. International Conference on Data Engineering, 2026 website / code / This work addresses the sync-compute dilemma in parallel graph-based vector retrieval via ScatterSearch, a synchronization-free intra-query parallel design with leader-guided pruning and work-stealing. |

|
Demystifying and Enhancing the Efficiency of Large Language Model Based Search AgentsTiannuo Yang*, Zebin Yao*, Bowen Jin, Lixiao Cui, et al. International Conference on Learning Representations, 2026 arxiv / code / 
We demystifies the key factors affecting the efficiency of LLM-based search agents and, based on these insights, designs SearchAgent-X to improve end-to-end efficiency without compromising generation quality. |

|
ALGAS: A Low-latency GPU-Accelerated Approximate Nearest Neighbor Search SystemYuanhui Chen, Lixiao Cui, Zebin Yao, Hao Zhou, et al. IEEE International Parallel & Distributed Processing Symposium, 2025 website / We present a low-latency GPU vector search system for small batch processing that optimizes query bubble via dynamic batching, reduces sorting overhead with beam extend, eliminates TopK-merging overhead through GPU-CPU cooperation, and enhances resource utilization with adaptive tuning. |
|
Design and source code from Jon Barron's website |